
A while ago, I wrote that AI needs teachers too.
At the time, I was thinking mostly about context. AI can summarize, explain, compare, retrieve, and generate, but it still needs someone to decide what information it should trust, which examples matter, what policies are current, and where the boundaries are.
I still believe that. But I think I stopped one step too early.
If AI needs teachers, then somebody also has to prepare what is being taught. Someone has to decide what is current, what is obsolete, which source wins when two documents disagree, how knowledge is structured, who owns it, and what happens when the answer is missing.
That is not prompting.
That is knowledge engineering.
And the more I think about it, the more I suspect that knowledge engineering may be one of the next important skills for L&D, not because every instructional designer suddenly needs a new title, but because it gives us a way to solve a problem we have been struggling with for years.
The engagement problem may be a design problem
L&D spends a lot of time worrying about engagement. People do not visit the platform, do not finish courses, ignore resources, or say they are too busy.
It is easy to interpret that as a learning problem.
I am not convinced it is.
Watch how people actually work when they get stuck. They search an old email, ask a colleague, look for a template, Google an error, ask AI, open a policy, message someone who solved the same problem last year, or just try something and see what happens.
They are learning all the time.
They are just not necessarily doing it inside the environment we decided to call “learning”.
That distinction matters because most people do not begin with an intention to learn. They begin with an intention to do something.
They are trying to prepare for a conversation, solve a workflow problem, understand a process, use a tool, make a decision, or figure out what went wrong.
So the better question is not always:
“What should we teach them?”
It is:
What are they trying to do, and what do they need in order to move forward?
That is where my thinking shifts from learning toward enablement.
A course is one possible answer
I am not trying to kill the course.
Some things genuinely need structure. Onboarding does. Compliance often does. Foundational knowledge does. Some skills need sequence, practice, feedback, and time.
But a course is still one answer to one kind of need.
Sometimes the person already understands the concept and just needs the current process. Sometimes the process itself is wrong. Sometimes the software changed. Sometimes the manager wants something different. Sometimes there are six versions of the same answer and nobody knows which one is current.
In those cases, training may not be the real problem.
The useful intervention might be a job aid, a better search result, a decision tree, a person, or an AI assistant that retrieves the right source at the right time.
The real work may be connecting all of those things.
That is where knowledge engineering starts to become useful language for L&D.
The work around the content
When I say knowledge engineering, I am not talking about creating more documents.
I am talking about the work around the documents.
Who decides what is authoritative? Who notices that the page everyone keeps finding is two versions behind? Who owns the terminology? What happens when two procedures disagree? How does a person know which answer to trust? How does an AI system know?
Those questions sit somewhere between instructional design, knowledge management, technical writing, operations, and AI.
But L&D already has useful instincts here.
We think about what people need to know, what can be removed, what should come first, where confusion appears, when an example helps, and what people need in order to apply something.
Knowledge engineering takes some of those instincts and moves them beyond the course.
It is less about designing one learning artifact and more about designing the knowledge environment around the work.
Then the interesting thing happens
This is where the idea becomes more than better knowledge management.
Humans and AI do not need knowledge in exactly the same form.
An AI system is perfectly happy with the boring version. Give it the rules, definitions, procedures, parameters, exceptions, constraints, current terminology, ownership, and source.
Humans usually need something else.
They want to know why something matters, which option makes sense, what usually goes wrong, what the trade-off is, what good looks like, and what they should do next.
For a while, I treated that as a tension. Now I think it may actually be the solution.
Build the knowledge environment for the machine, and let the machine render the human version on demand.
The underlying knowledge can be precise, structured, current, governed, and boring.
Then AI can translate it into something useful for the person asking the question.
Someone might ask, “I’m about to have this conversation with my employee. What should I keep in mind?”
Someone else might ask, “I haven’t done this process since last year. What changed?”
Another person might simply say, “Tell me what I need to do next.”
They are all drawing from the same source of truth, but they do not need the same answer.
The machine becomes the translation layer.
Maybe the way to improve human engagement is to stop designing everything primarily for humans
We have traditionally designed knowledge around the artifact we expect people to consume: the page, the PDF, the course, the portal, the video.
Then we try to convince people to visit those things.
What happens if we invert the model?
We build a safe, controlled, curated knowledge environment underneath. The sources are accurate, ownership is clear, obsolete material is removed, terminology is consistent, and important relationships are explicit.
Then AI becomes one of the interfaces into that environment.
The person does not necessarily need to know which page contained the answer. They need to know that the answer came from the right place.
That feels like a much more interesting L&D problem than producing another piece of content and hoping someone remembers where we put it.
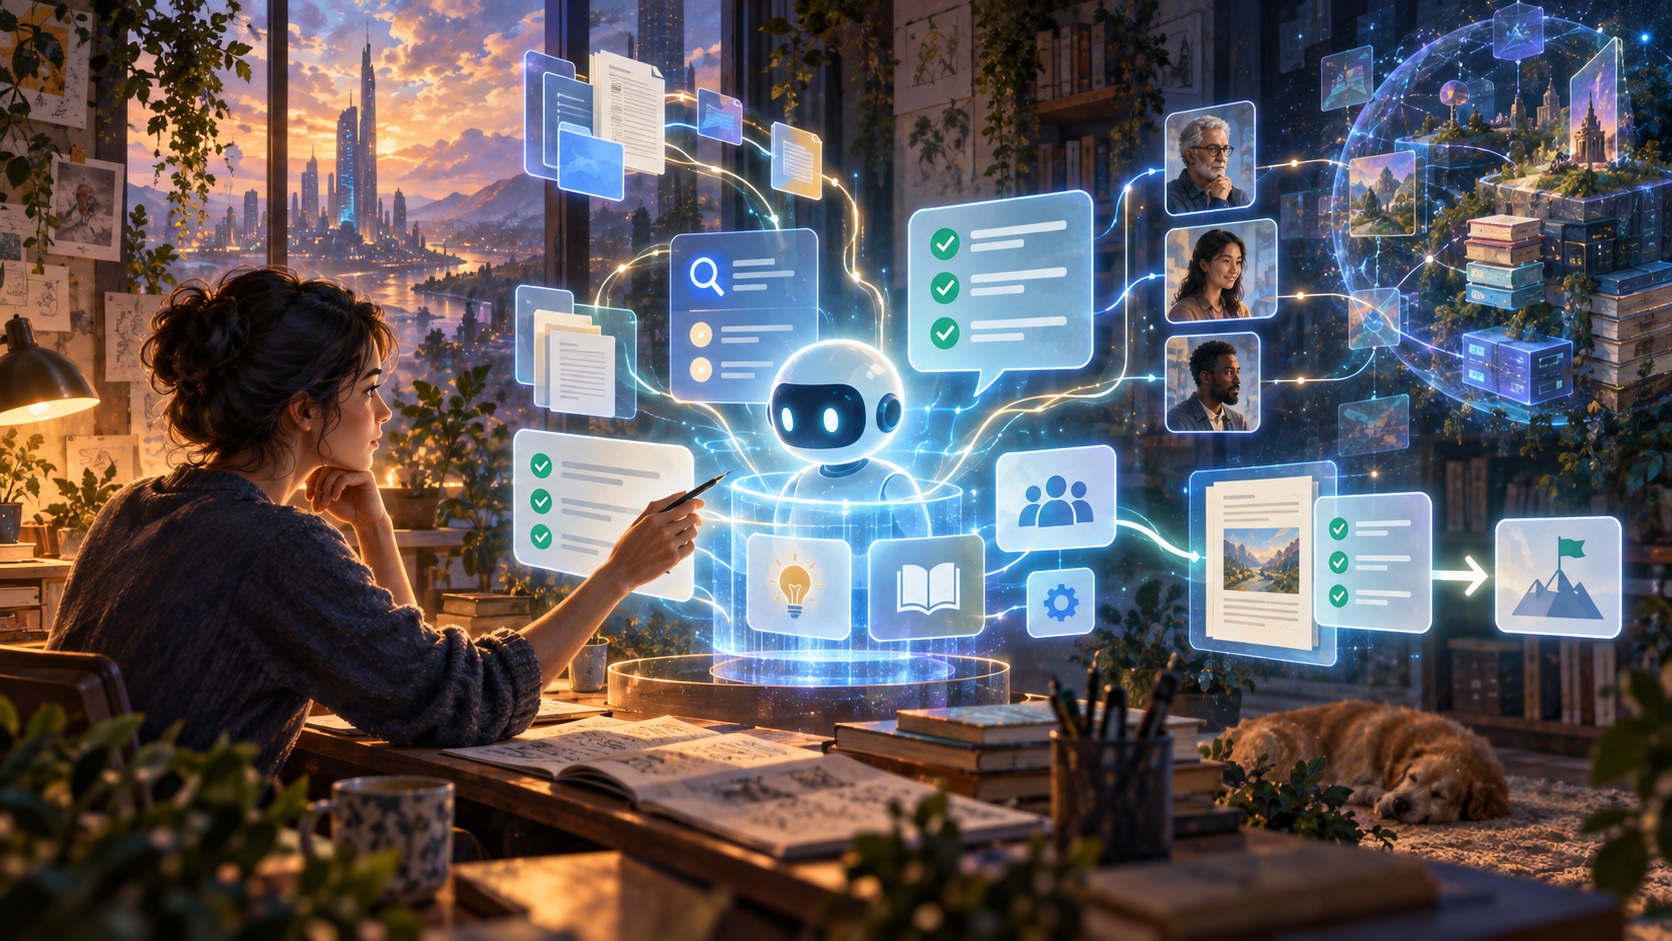
This is the enterprise version of my little curated worlds
This idea is familiar to me because I already work this way with local AI.
I like small, curated knowledge environments where I know what I gave the model, what it is allowed to rely on, and where the boundaries are.
I do not need the model to know everything.
I need it to know this world well enough to be useful inside it.
At my desk, that might mean a collection of sources, notes, transcripts, examples, and instructions around one topic.
At organizational scale, the principle is not that different.
The difference is the stakes.
Now hundreds or thousands of people may rely on that knowledge. AI agents may retrieve it automatically. One bad source can propagate much further than one bad answer in my own lab.
So the same things I care about locally become organizational design questions: what went in, who decided it was trustworthy, how it stays current, and what happens when the system does not know.
That is why knowledge engineering is not just the plumbing behind the AI.
It is what makes the AI safe enough to become part of enablement.
AI will amplify whatever we give it
Bad organizational knowledge is not new.
Every company has stale pages, duplicate procedures, mystery documents nobody wants to delete, and processes that changed while the documentation stayed behind.
Humans have learned to work around that mess.
We ask around. We notice that something looks old. We know that Maria probably understands the real process even if the official document says something different.
AI does not automatically have that organizational instinct.
If we tell it that the knowledge base is authoritative, it may treat whatever it retrieves as authoritative.
And if AI becomes the main interface through which people access that knowledge, curation stops being optional.
Who owns this? Is it still true? Which source wins? What does this term mean? When should the system say “I don’t know”? When should it send the employee to a person instead?
Those are not prompt-engineering questions.
They are knowledge-engineering questions.
AI should be the front door, not the whole house
There is an obvious risk here.
If AI becomes the default interface to organizational knowledge, it is easy to imagine a workplace where every question gets routed through a machine and human knowledge-sharing slowly disappears.
That is not what I want.
Sometimes the correct answer is a document. Sometimes it is a checklist. Sometimes it is a course. Sometimes it is another human being.
The colleague who remembers the history is part of the knowledge environment. The SME who understands the exception is part of it. The manager who can see the context is part of it.
A good system should know when the best retrieval result is actually a person’s name.
AI can be the front door without becoming the whole house.
That matters because enablement is not about replacing every path to knowledge with a chatbot.
It is about making the right path easier to find.
And not every moment should be frictionless
There is another boundary I think matters.
Enablement is mostly about performance moments.
Someone is trying to do something and needs support. In that situation, removing friction can be useful. Show the process, find the answer, identify the expert, and help them move forward.
Learning moments can be different.
Sometimes the friction is the point.
Sometimes people need to struggle with a problem, make a decision, practice, fail, reflect, and try again.
If AI immediately solves every difficulty, it can also remove the opportunity to develop the skill.
I do not see those ideas as contradictory.
Performance support should help people perform. Learning design should still create space for people to learn.
The real design question is knowing which moment you are in.
Maybe the useful metric is time-to-unstuck
Once I look at L&D through this lens, some traditional measures become less interesting.
I still care whether somebody completed required training.
But for an enablement environment, I am much more interested in time-to-unstuck.
Someone hits a problem. Can they describe it well enough to ask for help? Can the system find the right source? Can AI turn that source into something useful for this situation? Can it recognize when the answer is missing or when another person should be involved?
And then, most importantly, can the person get moving again?
That gives us better signals too.
If people keep asking the same question, maybe the process is unclear. If AI cannot answer something, maybe we found a knowledge gap. If everyone keeps getting routed to the same SME, maybe that expertise should be captured somewhere.
The questions people ask become a kind of live needs analysis.
That is much more useful to me than knowing that 86% of employees opened a page.
This is what I meant by AI needing teachers
So I keep coming back to that original article.
When I wrote AI needs teachers too, I was thinking about context and guidance.
Now I think the organizational version is bigger.
AI needs a knowledge environment worth learning from.
People need a way to access that knowledge without leaving the work every time they hit a problem.
Knowledge engineering builds the substrate. AI can become the retrieval and translation layer. Instructional design still handles the moments where people genuinely need to learn, practice, and develop capability.
Put those pieces together and the picture starts looking less like traditional learning management and much more like enablement.
That is the direction I find interesting.
Not a bigger course catalog. Not another prompt library. Not an AI assistant connected to every document we have ever created.
A curated environment where knowledge is trustworthy enough for machines, useful enough for humans, and close enough to the work to matter.
At my desk, I have been building small versions of this for a while without really having the organizational language for it.
Curated knowledge. Clear boundaries. AI as the interface. Human judgment still inside the loop.
The enterprise version is not fundamentally different.
It is just larger, messier, and more important.
And maybe that is the next L&D skill I have been looking for: knowledge engineering in service of enablement.